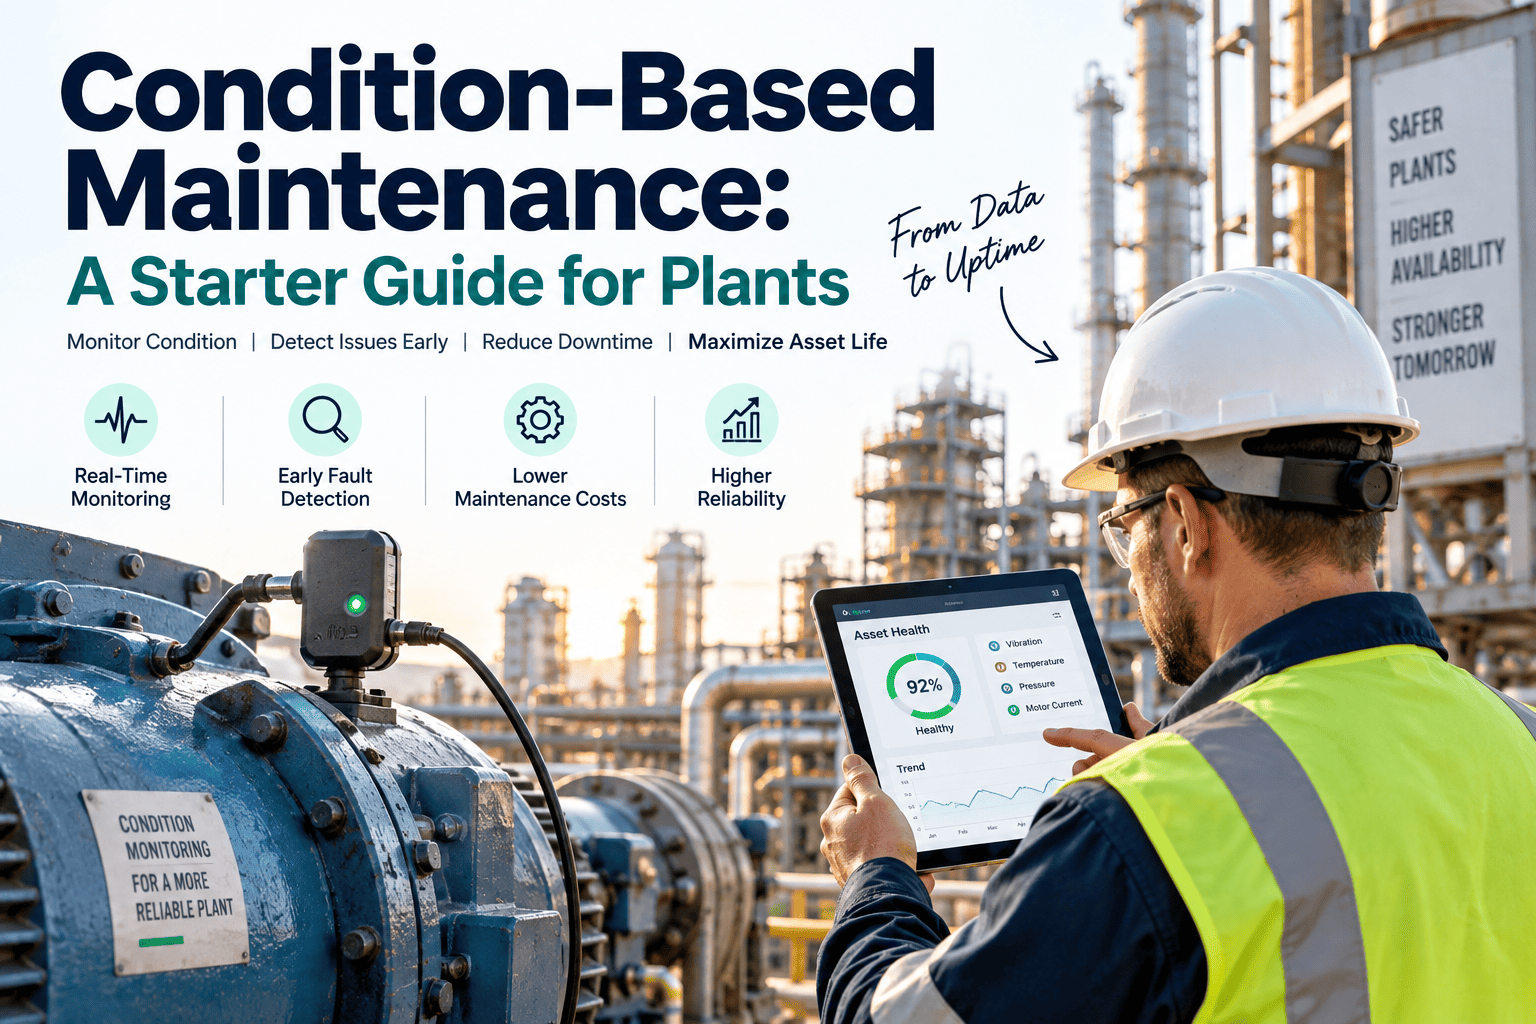
Almost every predictive maintenance pilot starts the same way: a handful of sensors go on a handful of critical assets, a dashboard lights up with promising trend lines, and everyone in the room agrees this is clearly the future. Then, months later, that same pilot is still running on the same three machines, the wider rollout keeps slipping to next quarter, and nobody can quite explain why the momentum disappeared. Oxmaint connects sensor data directly to real maintenance triggers and work orders, so a pilot has an actual path to becoming a programme instead of a permanent proof of concept. Start a free trial to see what a connected rollout looks like.
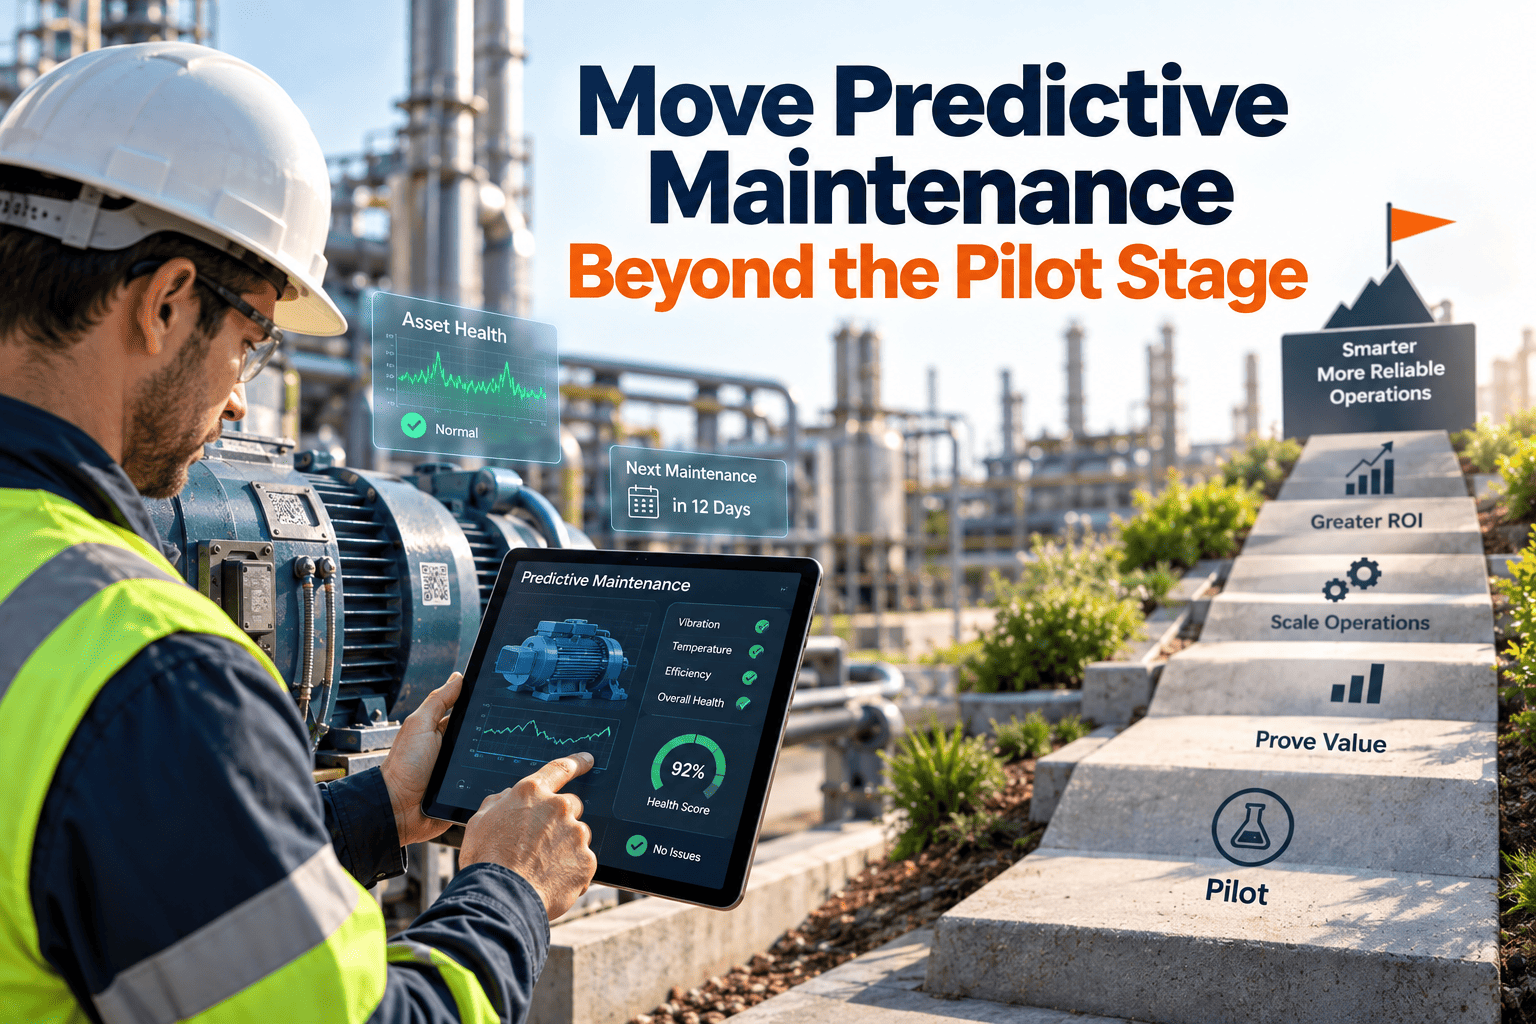
Move Predictive Maintenance Beyond the Pilot Stage
A pilot proves the technology works. It does not, by itself, prove that a maintenance team can act on the data fast enough to matter, and that gap is exactly where most predictive maintenance programmes quietly stall out before ever reaching real scale. Oxmaint closes that gap by turning sensor readings into assigned, trackable work the moment a real risk appears.
Why So Many Predictive Maintenance Pilots Never Leave the Lab
Predictive maintenance has been the most talked-about idea in industrial maintenance for years, and it has also been one of the hardest ideas to scale past a small proof of concept. The technology to capture vibration, temperature, and condition data has matured quickly, but the organisational side of turning that data into action has lagged behind, leaving a lot of promising pilots stuck running on the same few assets long after the initial budget approval was signed off.
The most common failure point is not the sensors and it is not the underlying model. It is the handoff between a data platform that raises an alert and a maintenance team that has to decide, under real time pressure, whether that alert is worth acting on right now. When that handoff runs through a separate dashboard nobody checks daily, or a spreadsheet someone has to remember to update by hand, the alert simply dies quietly, and the case for expanding the pilot gets harder to make with every cycle that passes.
Scaling successfully means treating the alert-to-work-order pathway as the actual product, not the sensor data itself. Oxmaint is built around that pathway directly, so every meaningful signal becomes a scheduled, assigned piece of work automatically, and the case for expanding coverage to more assets gets easier to make with every cycle instead of harder, turning a stalled pilot into a programme with real momentum behind it.
Four Reasons a Pilot Stalls Before It Ever Scales
None of these reasons are about the underlying sensor technology being unreliable or poorly calibrated. They are almost always about what happens, or more often does not happen, after a reading crosses a threshold and someone on the team has to decide what to do next.
Turn Sensor Data Into Work Orders Automatically
Oxmaint connects condition monitoring directly to maintenance workflows, so a meaningful signal becomes assigned, trackable work the moment it crosses a real threshold, not a screen nobody has time to check between shifts.
How a Predictive Maintenance Programme Actually Scales
Scaling is not a single decision to expand from three assets to three hundred overnight. It is a sequence of smaller, provable steps, each one building the confidence and the workflow muscle needed for the next, so the programme grows in a way the team can actually sustain rather than one that collapses under its own weight after the first setback.
The Building Blocks Every Scaled Programme Shares
Programmes that successfully expand past the pilot stage tend to share the same handful of foundations, regardless of industry or asset type. None of these require replacing the sensor hardware already installed; they are almost entirely about how the data is routed once it leaves the sensor.
None of these foundations require a large upfront project. Most teams put the first two in place within a single planning cycle, using the alerts already coming off their existing pilot assets, and then layer in escalation paths and feedback loops as confidence in the workflow builds across the wider maintenance team.
What Staying Stuck in Pilot Mode Actually Costs
A pilot that never scales is not a neutral outcome. The sensors and platform costs are still being paid for every month, the failures on unmonitored assets are still happening across the rest of the fleet, and the credibility of the wider predictive maintenance initiative erodes a little more with every budget cycle it fails to show measurable progress.
A Stalled Pilot vs a Programme Built to Scale
The difference below is rarely about better sensors on the shop floor. It is almost always about whether the workflow connecting a reading to a repair was built to handle one small asset group or built with growth in mind from the start.
| Element | Stalled Pilot | Programme Built to Scale |
|---|---|---|
| Alert Handling | Reviewed manually on a separate dashboard | Routed automatically into an assigned work order |
| Alert Volume | Every signal treated with equal urgency | Ranked by severity and asset criticality |
| Ownership | Unclear who is responsible for acting | Assigned automatically to the right technician |
| Business Case | Proven only on the original pilot assets | Tracked continuously and reusable for expansion |
| Expansion Path | Requires a fresh evaluation each time | Repeats a proven workflow on new asset tiers |
Moving from the left column to the right one does not require ripping out existing sensors or the condition monitoring investment already made. It requires connecting what is already being measured to a workflow that actually turns a reading into scheduled, accountable work, which is precisely the layer most stalled pilots were missing from day one of the rollout.
What Teams See Once the Rollout Actually Moves
These outcomes tend to show up once alerts are flowing into real work orders and the first expansion beyond the original pilot group has actually happened on the ground.
Scaling Predictive Maintenance — What Teams Ask
A few honest answers to the questions maintenance and reliability leaders most often raise before committing budget to a wider predictive maintenance rollout.
Does Oxmaint replace our existing condition monitoring sensors? +
What is usually the biggest reason a pilot fails to scale? +
How long does it typically take to move from pilot to a wider rollout? +
Can this work across multiple sites with different asset types? +
How do we build the business case to expand beyond the pilot? +
Give Your Pilot a Real Path to Becoming a Programme
Oxmaint connects the sensor data you already have to real, assigned maintenance work, so every signal has somewhere useful to go, and every avoided failure builds the case for the next stage of the rollout across the fleet.